Meta Llama 4-Light Review: Can Local Agentic AI Replace Wrappers?
Meta Llama 4-Light Review: Can Local Agentic AI Replace Wrappers?
Yes — Meta Llama 4-Light's 8B model can run agentic loops locally without heavy orchestration wrappers, if you stay within its limits. I tested the model on a single consumer GPU to find out where it holds up and where it breaks.
Meta just dropped Llama 4-Light unexpectedly, and the developer community is reacting strongly. I stayed up until 3 AM running the 8B model on an RTX 4090 to see if the hype matches reality.
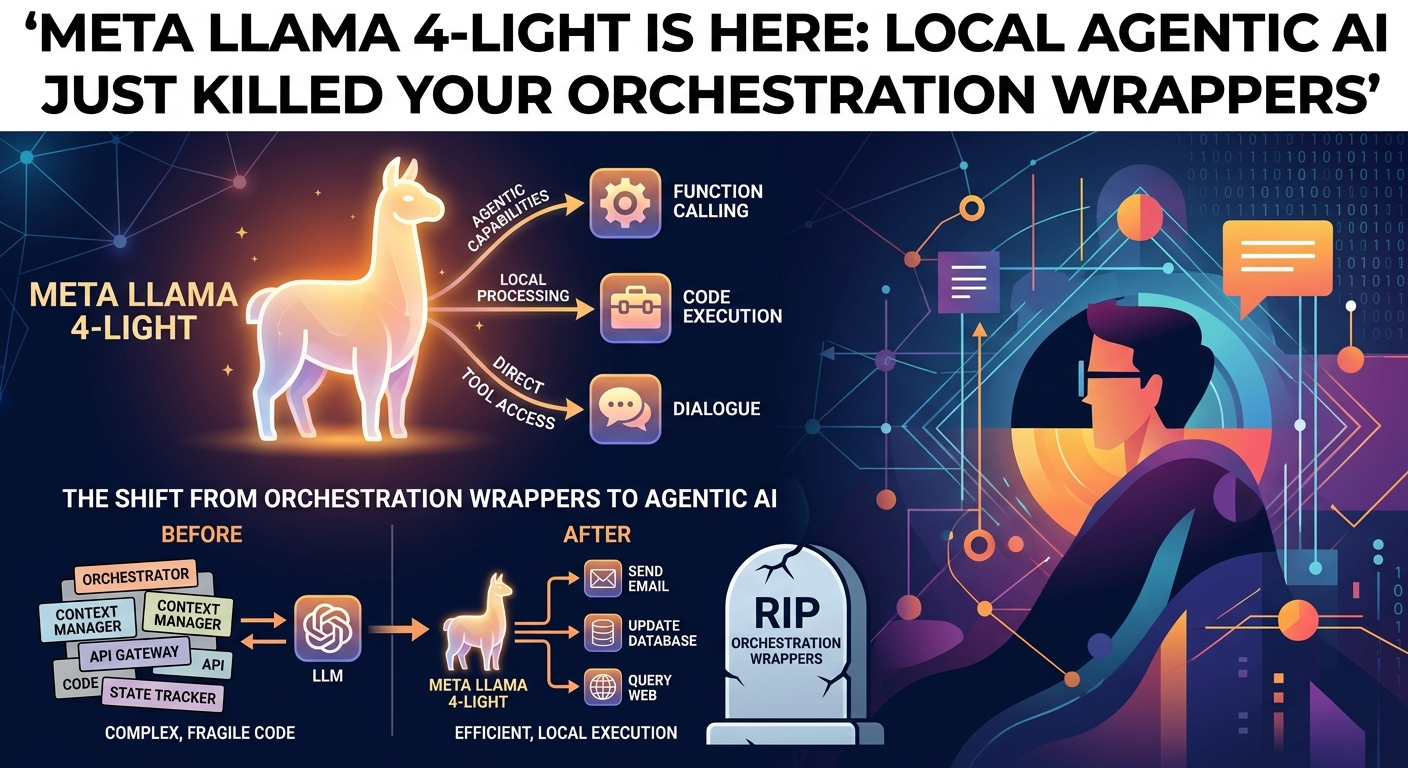
For months, getting local models to call tools reliably meant dragging around bloated orchestration frameworks. Llama 4-Light changes that by baking reasoning loops and native tool-calling directly into the model's weights.
What's Under the Hood
Meta's new architecture prioritizes execution over text generation. The 8B model isn't a slightly smarter Llama 3 — it's a rebuilt system optimized for agentic workloads.
- Native Tool-Calling Loops: The model runs a system-action-observation cycle directly, without a middleman framework parsing its thoughts before calling an API.
- Fast Local Latency: On a standard RTX 4090, the 8B variant pushes over 110 tokens per second with near-instant time-to-first-token.
- Self-Correction Weights: When a tool returns an error, Llama 4-Light catches its own syntax mistake and rewrites the query immediately.
This lets you drop the massive Python packages that slow down projects. The intelligence sits inside the model where it belongs.
Where It Actually Shines
I ran two targeted tests to see whether Llama 4-Light could handle real production tasks.
Autonomous Code Refactoring
I gave the model a messy legacy Node.js repository and access to a local bash tool. It identified three deprecated packages, looked up modern replacements via local docs, wrote a migration script, and ran the test suite. It failed twice from dependency conflicts but fixed its own code both times before completing the task.
Live Local SQL Querying
I connected the 8B model to an active SQLite database with mocked customer data. Instead of generating raw SQL and waiting for manual execution, the model dynamically ran queries, checked results, and refined its search criteria until it found the exact log entry requested.
The Hard Limitations
It isn't all magic. Before you remove your API keys, consider the trade-offs.
The context window is partly a mirage. Meta claims 128k tokens, but reasoning accuracy drops sharply after about 24k tokens. Pushing past 32k caused the model to forget active tool schemas and hallucinate old Python imports.
VRAM spikes aggressively during deep reasoning loops. The model keeps a running memory of internal thoughts, which can saturate your hardware quickly without strict execution limits. An infinite self-correction cycle can easily lock up your GPU.
The Verdict
Llama 4-Light proves that open-source AI is no longer playing catch-up. By moving agentic logic from the software layer directly into model weights, Meta has made local, private AI agents viable for everyday developers.
Grab the weights from Hugging Face, spin up llama.cpp, and try it yourself. Just set a hard limit on your execution loops before your GPU hits its limits.